 Engineering
MSA Service Boundaries Designed for Splitting Work Among AI Agents
· AlgoSu
- #ai-dev
- #architecture
- #msa
- #kubernetes
Problem
Even for a solo-built service, a monolith meant one agent had to understand the entire codebase, and accuracy dropped as its context widened.
Decision
Split services by data ownership so they line up with agent responsibility boundaries; humans decide service boundaries, communication, auth, and deployment, and AI executes.
Result
Humans set the direction and AI filled in the details, keeping 6 services at consistent quality even working solo.
Why MSA
MSA (microservice architecture) means building an application as several small services instead of one large one.
When designing AlgoSu, the first question wasn't about architecture patterns. It was how to delegate work to AI agents.
With a monolith, a single agent would need to understand the entire codebase. Fixing auth logic would require knowing submission logic, understanding the DB schema, and more. I'd already seen that the shorter and narrower an agent's instructions were, the better it followed the key ones.
What if, instead, we split services into small units? The narrower the domain an AI manages, the clearer its role becomes, and the more accurate its decisions within a single service. The auth & security agent (Gatekeeper) handles only the Gateway, the database agent (Librarian) only DB schemas, and the submission-flow agent (Conductor) only Submission. Aligning agent responsibility boundaries with service boundaries was the core reason for choosing MSA.
Of course, MSA is complex. Inter-service communication, distributed transactions, deployment pipelines: problems you'd never have to worry about in a monolith. But if AI agents can share that complexity, the tradeoff holds up.
How Services Were Split
The criteria for splitting services were simple. If data ownership differs, split the service.
Identity manages user data, Submission manages code submissions, Problem manages problems, and each owns its own database. Because splitting later would be migration hell, we split the databases per service early on. For a while, though, the Gateway still connected directly to Identity's DB; only after we built an API in the Identity service and cut that connection did the rule that no service touches another service's DB (Database per Service) actually hold.
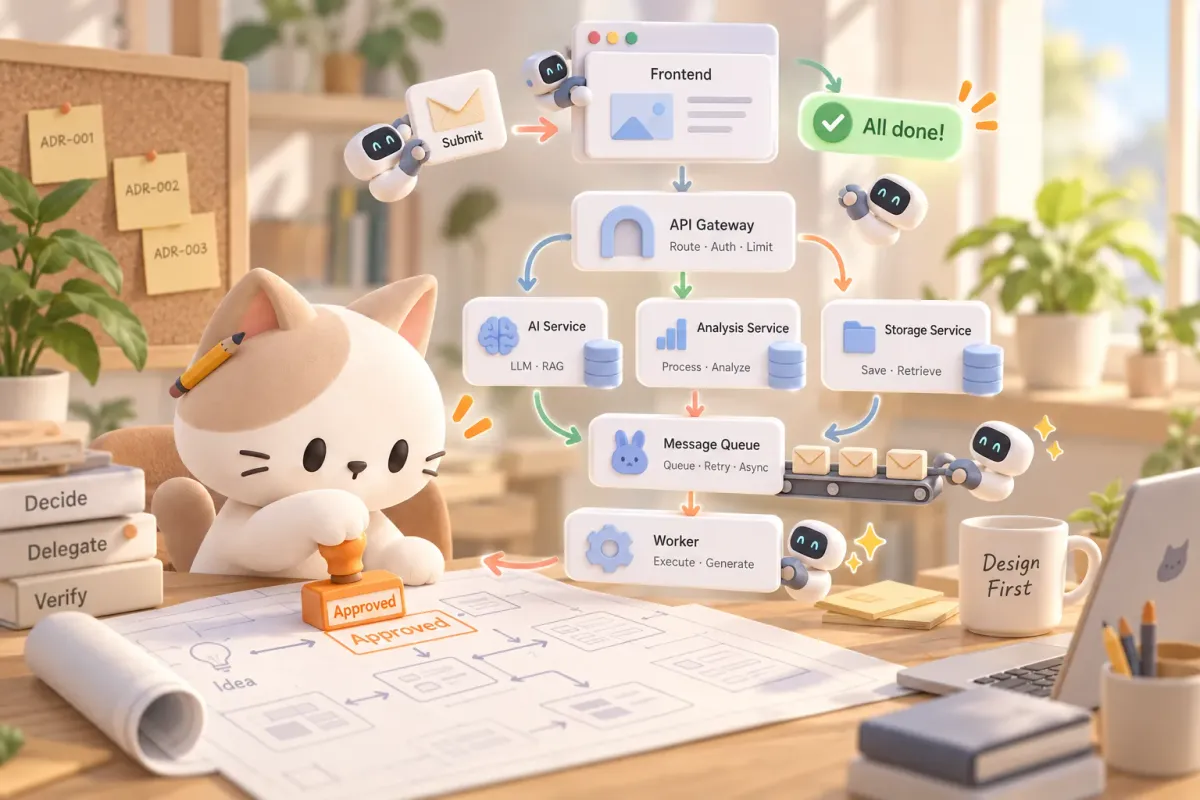
Async tasks were extracted into separate workers. GitHub pushes and AI analysis are long-running operations, so we couldn't make users wait. We made GitHub Worker and AI Analysis into independent services, connected via RabbitMQ.
The Gateway is the sole external entry point. It handles auth, routing, rate limiting, and SSE (Server-Sent Events, the server pushing real-time updates to the browser) streaming. All other services communicate only within the cluster.
k3s on OCI ARM (24GB · 4 OCPU)
| Service | Stack | Port | Owns |
|---|---|---|---|
| Frontend | Next.js 15 · App Router | 3001 | Tailwind, shadcn/ui, SSE subscription |
| Gateway | NestJS | 3000 | OAuth + JWT, X-Internal-Key issuance, rate limit, SSE |
| Identity | NestJS · identity_db | 3004 | Users / studies / notifications / share links |
| Submission | NestJS · submission_db | 3003 | Saga Orchestrator · code review |
| Problem | NestJS · problem_db | 3002 | Problem CRUD · deadlines |
| GitHub Worker | Node.js · prefetch=2 | 9100 | submission.github_push queue → GitHub push |
| AI Analysis | FastAPI · Circuit Breaker | 8000 | submission.ai_analysis queue → Claude API |
| Claude API | claude-haiku-4-5-20251001 (the model the service's AI code review feature calls) | None | MAX_TOKENS=8192, 4-step JSON fallback parsing (if parsing the response JSON fails, it falls back to the next method, up to four) |
In this structure, the division of AI agent responsibilities fell into place naturally. Most agents own a single service: the security agent owns the Gateway, the submission-flow agent owns Submission, the problem agent owns Problem, and so on. Work that spans several services, like databases and infrastructure, got its own owners. Since service boundaries became responsibility boundaries for most agents, the confusion of "whose job is this?" disappears.
Choosing Communication Patterns
Once services are split, you need to decide how they talk to each other. We picked from four patterns based on use case.
Sync HTTP
Immediate response (Gateway → services)
RabbitMQ async
Long-running tasks (GitHub push, AI)
Redis Pub/Sub
Real-time event propagation
SSE
Real-time streaming to the browser
Synchronous HTTP is used when an immediate response is needed. Calls from the Gateway to Identity, Submission, and Problem fall here. Internal calls carry an X-Internal-Key header to block external access. The key validation logic was designed by the security agent, which even applied crypto.timingSafeEqual on its own to prevent timing attacks.
RabbitMQ async messaging is used for long-running tasks. If we processed GitHub pushes and AI analysis synchronously after submission, users would wait over 30 seconds. With MQ-based async processing, we can respond immediately after submission. GitHub Worker's prefetch=2 (take at most two jobs at a time) was proposed by the infrastructure agent (Architect). It is a concurrency limit that accounts for GitHub API rate limits and OCI Free Tier resources.
Redis Pub/Sub is used for real-time event propagation between services. Every time a submission status changes, a message is published to the submission:status:{id} channel, and the Gateway's SSE Controller, which handles SSE connections, subscribes to it.
SSE is the final leg that streams data in real-time to the browser. Max connection time of 5 minutes, 30-second heartbeat, ownership verification: the security and submission-flow agents built these safeguards together. One notable issue: creating a Redis subscriber per SSE connection would exhaust the connection pool. Solving it with a shared subscriber pattern, where all connections use one subscriber, was the submission-flow agent's call.
The choice of each communication pattern was made by a human. "GitHub push after submission must be async" is an architectural decision. But the detailed design that carries out that decision was filled in by AI agents.
One Submission's Journey
Let's trace what actually happens with a single code submission to see this architecture in action.
When a user clicks "Submit," the Gateway validates the JWT, and the Submission Service's Saga Orchestrator manages the entire flow. The Saga pattern runs work that spans several services step by step, and when a step fails, it rolls back or skips in a defined way.
Saga state transitions
In this Saga design, what humans decided and what AI executed are clearly separated.
What humans decided
The order of saving to DB first, then publishing to MQ. If a service restarts, the record remains in the DB but the MQ message is lost. If the message went out first and the service died before saving, there would be work with no record, so the DB always comes first. This ordering, which keeps work from being lost, is an architectural principle, not something AI should decide on its own.
What AI (the submission-flow agent) executed
Optimistic locking to prevent backward transitions. Every state transition includes a WHERE sagaStep = currentStep condition to prevent duplicate processing. The same agent designed per-step timeouts and retries (5 minutes for DB_SAVED, 15 for GITHUB_QUEUED, 30 for AI_QUEUED). It also built recovery logic that automatically resumes incomplete Sagas from the last hour when a service restarts.
The human established the principle: "data must never be lost, even on failure." The AI built the concrete mechanisms to uphold that principle.
Who Decided Auth and Deploys
The remaining architectural decisions follow the same pattern. Humans set the direction; AI executes.
Auth: Whether to use httpOnly cookies or localStorage was a human decision. The reason was defense against XSS attacks. But details like the implementation of the OAuth flow, the automatic JWT renewal logic (TokenRefreshInterceptor, 5 minutes before expiry), and pinning the algorithm to HS256 were carried out by the security agent following security principles.
Security: The principle "All containers run as non-root, and privilege escalation is blocked" was set by a human. The infrastructure agent applied it consistently across every k8s (Kubernetes) manifest. A read-only file system (readOnlyRootFilesystem), every Linux capability removed (capabilities.drop: ALL), and temporary writable space (emptyDir) only on paths that truly need it. Applying identical security settings across 6 services without missing a single one is easy to slip up on when doing it alone. Applying default-deny NetworkPolicy and whitelisting only required communication follows the same logic.
Deployment: Choosing GitOps was a human decision. GitOps means writing down "what should run in the cluster" in a Git repository and letting a tool keep the cluster in line with it. When you push to main, GitHub Actions builds ARM64 images and pushes them to GitHub's container registry (GHCR) with main-{git-sha} tags. Then ArgoCD, a tool that applies what is in Git to the cluster, deploys them to the k3s cluster. Decisions like never using latest tags, guaranteeing zero-downtime deployment with maxUnavailable: 0 in RollingUpdate, running DB migrations via initContainer before the app starts were designed by the infrastructure agent following infrastructure principles.
Resource allocation on OCI ARM Free Tier follows the same pattern. Within the constraints of 24GB RAM and 4 OCPU, the infrastructure agent decided how to split each service's request/limit (guaranteed and maximum resources). AI Analysis is the only service with a 2Gi memory limit, a decision based on measured data showing that parsing Claude API responses requires significant memory.
The Boundaries of Design
The most important thing I discovered while designing MSA with AI was boundaries.
There are design decisions you can delegate to AI, and there are ones humans must make. Architectural directions like "Split databases per service," "handle external API calls asynchronously," and "use httpOnly cookies for auth" require understanding business context and tradeoffs. That's still too broad a domain for AI to judge on its own.
On the other hand, the execution after the direction is set (implementing optimistic locking, consistently applying security settings, tuning timeout values, detailed communication pattern design) is something AI does better than humans. It doesn't miss anything, stays consistent, and applies the same principles across 6 services uniformly.
So was choosing MSA the right call? We split services to make AI agent roles clear, and in practice, management became easier as agent responsibility boundaries aligned with service boundaries. Of course, the inherent complexity of MSA remains. But with AI sharing that complexity, I was able to maintain 6 services at a consistent quality level, even working solo.
There's no single right answer in architecture. But one thing is certain: when "developing with AI" becomes a premise, the architecture that fits that premise changes.