 AI Agents
Building and Running a Team of 12 AI Agents for Solo Development
· AlgoSu
- #ai-dev
- #agent
- #orchestration
- #claude-code
A Platform I Wanted to Build
Running an algorithm study group, the same frustrations kept coming back. Assigning problems, checking submissions, requesting code reviews. Every week, the same tasks, done by hand.
As the group grew, the management overhead grew exponentially. The thought came naturally: "It'd be great if there were a platform that automated all this."
Around then, I came across the idea of AI agent orchestration: give several AI agents different roles and have them work together as one system. The more I read, the more I wondered what would happen if I applied it to building a real service.
So I decided to try it. I would build the study platform alone, as a set of small services (an MSA, or microservice architecture), and run AI agents as my teammates.
Problem
Building alone is fast, but juggling 6 services left me without enough hands to keep both productivity and consistency.
Decision
I grew the team from 8 agents to 12 and specialized their roles. Shared rules went into one file every agent reads first (persona-base.md); each agent kept only the knowledge of its own area.
Result
It paid off in preventing a DB incident, catching leftover insecure code, and cutting the time it took to find past decisions (one from three months earlier in five seconds). Work ordering, and the balance between control and autonomy, are still being refined.
Limits of Building Alone
The walls showed up quickly. Not because I couldn't write the code, but because it's hard to keep both productivity and consistency when you're alone.
The Limits of Productivity
Working across 6 microservices (Gateway, Identity, Submission, Problem, GitHub Worker, AI Analysis) means a lot of context switching.
In the morning I'm designing a Saga (a way to run a task across several services step by step, and undo the steps if one fails). In the afternoon I'm wiring up SSE, which lets the server push real-time updates to the browser. In the evening I'm editing Kubernetes (k8s) deployment files.
When I come back to the Saga the next day, the reasons behind yesterday's decisions have faded. Time spent re-reading code piles up, and real progress slows down.
The Absence of Consistency
When you work alone, your standards wobble. "Just hardcode it this once." "I'll write the tests later." With no one to stop you, it's easy to give in.
Commit conventions, file structure, error handling: they drift a little every day. With 6 services, the inconsistencies multiply by six.
Both problems pointed at the same thing. One person's head can't hold the whole system's context and standards at once.
First Try: 8 Agents
I built the agent setup on Claude Code, Anthropic's coding-agent tool. All the agents run on Anthropic's Claude models. It started with 8 agents, each mapped to one role on a real development team.
- Oracle: the lead agent. Splits up the work and coordinates.
- Conductor: the code-submission flow
- Gatekeeper: auth and security
- Librarian: the database
- Architect: infrastructure
- Postman: GitHub integration
- Curator: problem management
- Herald: the frontend
At this stage I gave each agent a complete persona. Role description, behavior rules, code conventions, security principles: everything went into one agent's prompt. I expected that once an agent had an identity ("this is who you are"), it would work out the rest.
How to Design the Workflow
Creating the agents was the easy part. The hard part was in what order, and how, they should work together. At first I called agents whenever I needed them, and the limits showed up fast.
The agents couldn't carry context. Call the same agent twice, and it didn't remember what it had decided the first time. I solved this later by having decisions written down, as you'll see below.
The order of work between agents got tangled too. If Conductor (submission flow) changed an API before Librarian (database) changed the schema, the types no longer matched.
From Personas to Rules
The bigger problem was consistency. With a full persona for each of the 8 agents, the shared rules started to drift apart. Conductor kept functions under 20 lines; Herald (frontend) wrote 30-line ones. Commit message formats differed slightly from agent to agent.
So I pulled the shared rules into one file: persona-base.md, the shared rules file every agent must read before starting work. Code conventions, security principles, reporting structure, and escalation paths (how a problem gets passed upward) all live there. Each agent's own prompt kept only knowledge specific to its area.
It also cut how much each agent had to read at once (its context). With shorter prompts, the agents followed the core instructions better. And with the shared rules in one place, a change only had to be made once.
From 8 to 12
Running with 8 agents, the gaps started to show.
First, documents were piling up with no one to manage them: the decision records (ADRs) written each sprint (a short work cycle), MEMORY.md (a memory file loaded automatically every session), and the history of prompt changes. Librarian was handling these on the side, but managing a database schema and managing documents are different jobs. So I split out a documentation agent, Scribe.
Second, adding the AI analysis feature called for an AI-analysis agent, Sensei. Claude API calls, the Circuit Breaker pattern (cutting off calls so a failure doesn't spread), parsing responses: that was too much for Herald to carry on top of the frontend.
Third, as the frontend grew, a similar problem appeared. Herald owned both page development and the design system, but component specs and page logic belonged apart. A design-system agent, Palette, took over the design system.
Last came Scout, the user-testing agent. Nobody was checking the agents' output from the user's point of view. I needed someone to catch features that worked but felt awkward to use.
The twelve are split into three priority tiers (echelons).
Tier 1
Mission Critical
The areas where everything stops if they break. These use the most powerful Claude model at the time (Opus). Oracle, the lead agent, belongs here, along with Conductor, Gatekeeper, and Librarian.
Tier 2
Core
Infrastructure and core business logic, handled by Architect, Postman, Curator, and Scribe.
Tier 3
Enhancement
Work that adds value to the service. It starts only after tiers 1 and 2 are stable. Sensei, Herald, Palette, and Scout handle it.
Twelve agents in three priority tiers (echelons)
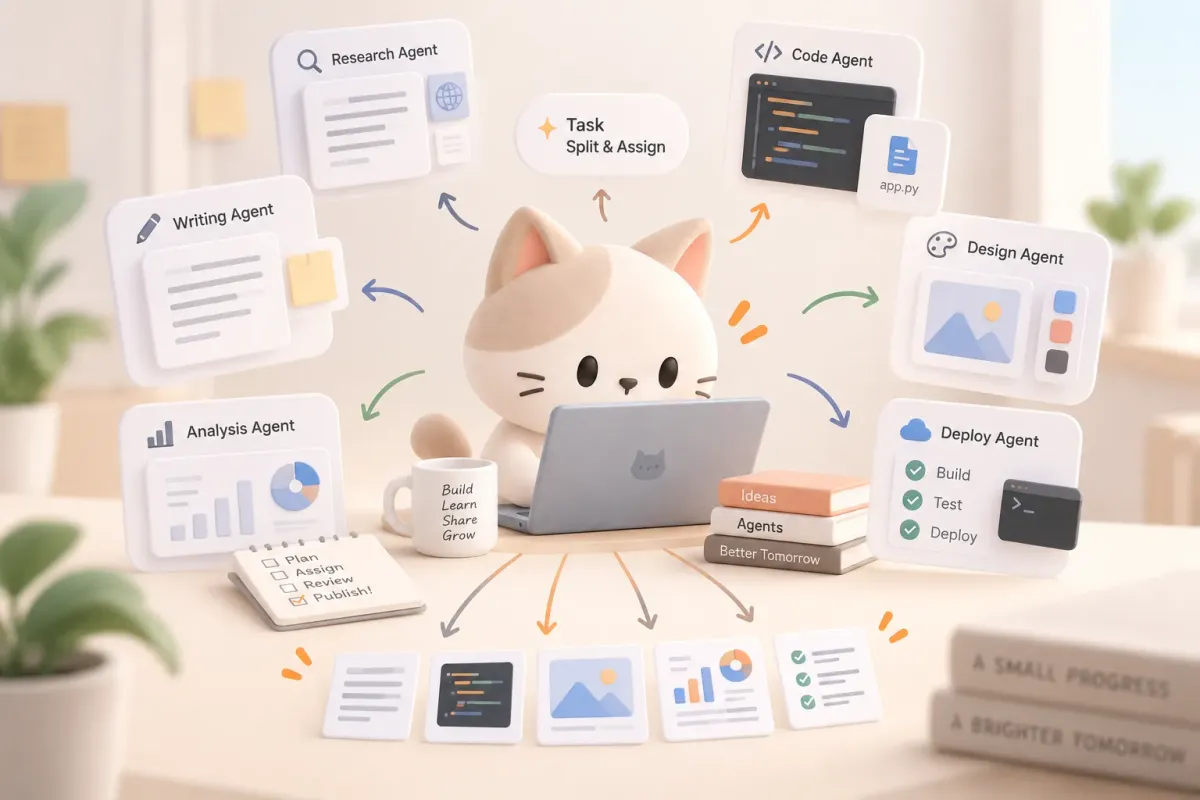
I (the PM) talk only to Oracle. Oracle analyzes a task, hands it to the right agent, then gathers the results and reports back. Agents don't talk to each other directly. When they conflict, Oracle mediates.
Effects Felt in Practice
The Database Incident That Didn't Happen
I was changing the database schema of the Problem service and wanted to rename a column. Librarian's rules stopped me.
Expand-Contract pattern enforced. Column deletion/rename must use a 3-phase deployment.
Always assume a situation where old and new versions coexist during Rolling Updates.
During a rolling update, servers are replaced one at a time, so old and new code run side by side. The rule says: don't rename in place. Widen first (Expand), and narrow later (Contract).
So instead of a simple rename, I did it in three phases: (1) add a new column, (2) copy the data and switch the application code, (3) drop the old column. It felt tedious, but it finished with zero downtime in production. On my own, I would have thought "a rename will be fine" and moved on.
The Security Leftovers Gatekeeper Caught
While refactoring the authentication logic, some code was still storing tokens in the browser's localStorage. Even after switching to httpOnly cookies (which JavaScript can't read), traces of the old approach were hiding all over the codebase. The rules of Gatekeeper, the auth and security agent, caught them.
SSE authentication:
EventSource(url, { withCredentials: true }). localStorage tokens cannot be used in an httpOnly Cookie environment.
Sensitive data strictly prohibited: raw JWT, X-Internal-Key, OAuth tokens.
(X-Internal-Key is an internal auth key used only between services.) Because of this rule, the code that still read tokens from localStorage was flagged as a violation.
A person might think "I already fixed that, it's probably fine" and move on. An agent checks everything, every time.
Context That Doesn't Disappear
Over 67 sprints, I asked "why did we decide this?" more times than I can count. Every decision was recorded in MEMORY.md and the sprint decision records that Scribe maintains. So I could find a decision from three months ago in five seconds.
The scariest thing about building alone isn't a feature that doesn't work. It's forgetting why you built it that way. When the context is gone, you repeat old mistakes or reconsider alternatives you already ruled out. The agent setup solved this structurally.
Trial and Error in Workflow Design
Even with agents, getting the calling order wrong made them useless. Early on, I called whichever agent I needed on the spot. As the order got tangled, one agent's output kept breaking another agent's assumptions.
Eventually I made the priority tiers the execution order too.
- Tier 1 (Oracle, Conductor, Gatekeeper, Librarian) sets up the foundation and safety nets first,
- tier 2 (Architect, Postman, Curator, Scribe) builds the features,
- and tier 3 (Sensei, Herald, Palette, Scout) finishes the work.
Sticking to this order cut dependency conflicts sharply.
Tier 1
Infrastructure · safety netsTier 2
Features · business logicTier 3
UX · analysis · finishing
The Direction Ahead
Running this setup, one question keeps coming back. How do you keep quality high while controlling AI and raising productivity?
Tighten control, and productivity drops. Reviewing every agent's output by hand is no different from doing it all yourself. Loosen it, and quality wavers. Sooner or later an agent makes a decision on its own that clashes with the overall architecture.
The balance I've found so far has three parts. Draw clear role boundaries, keep the shared rules in one place, and leave the escalation path open.
Inside its own area, an agent decides for itself. Outside it, the agent must go through Oracle. The rules live in a single file (a single source of truth, or SSoT), so they can't drift apart. Hard calls come up to a human.
I don't know yet whether this is the right answer. Each sprint brings new problems, and I keep adjusting the setup bit by bit. One thing is certain: this is a kind of thinking I never would have done on my own.
What Doing It Changed
Reading about AI agent orchestration and actually doing it are completely different experiences. On paper, it boils down to "divide the roles and write the rules." In reality, the setup took shape through dozens of incidents: tangled workflows, lost context, rules drifting apart.
If I hadn't tried, I'd have stayed at the shallow idea that "AI writes code for you." Because I did, I learned things. What to hand to agents and what to do myself. Where to draw the line between control and autonomy. How to combine one person's judgment with twelve agents' execution.
In the end, what mattered was starting.