 Engineering
A 15-Job CI Pipeline for Verifying AI-Written Code
· AlgoSu
- #ai-dev
- #ci-cd
- #github-actions
- #gitops
Shipping AI Code Unchecked
Once, I committed AI-generated code and hit git push. The code itself was fine. Tests passed, lint was clean. But there was one problem: I had amended the commit with git commit --amend and force-pushed.
CI ran, but nothing got built. Files had clearly changed, yet CI determined there were "no changes." dorny/paths-filter, a GitHub Action that looks at changed file paths to tell which services changed, couldn't properly detect the diff from a force-pushed commit. When the first gate of the deployment pipeline (change detection) is breached, every subsequent check doesn't even execute.
The faster AI writes code, the less a person can read every line. So verification had to fall to the pipeline rather than human eyes, and the pipeline's very first gate gave way to a single force-push. After this incident, force-push (amend) was banned across the entire project, and I started building the verification pipeline tighter.
Problem
AI writes code faster than a person can read it all, so verification had to rely on CI, yet a single force-push broke through CI's first gate (change detection) and nothing got built.
Decision
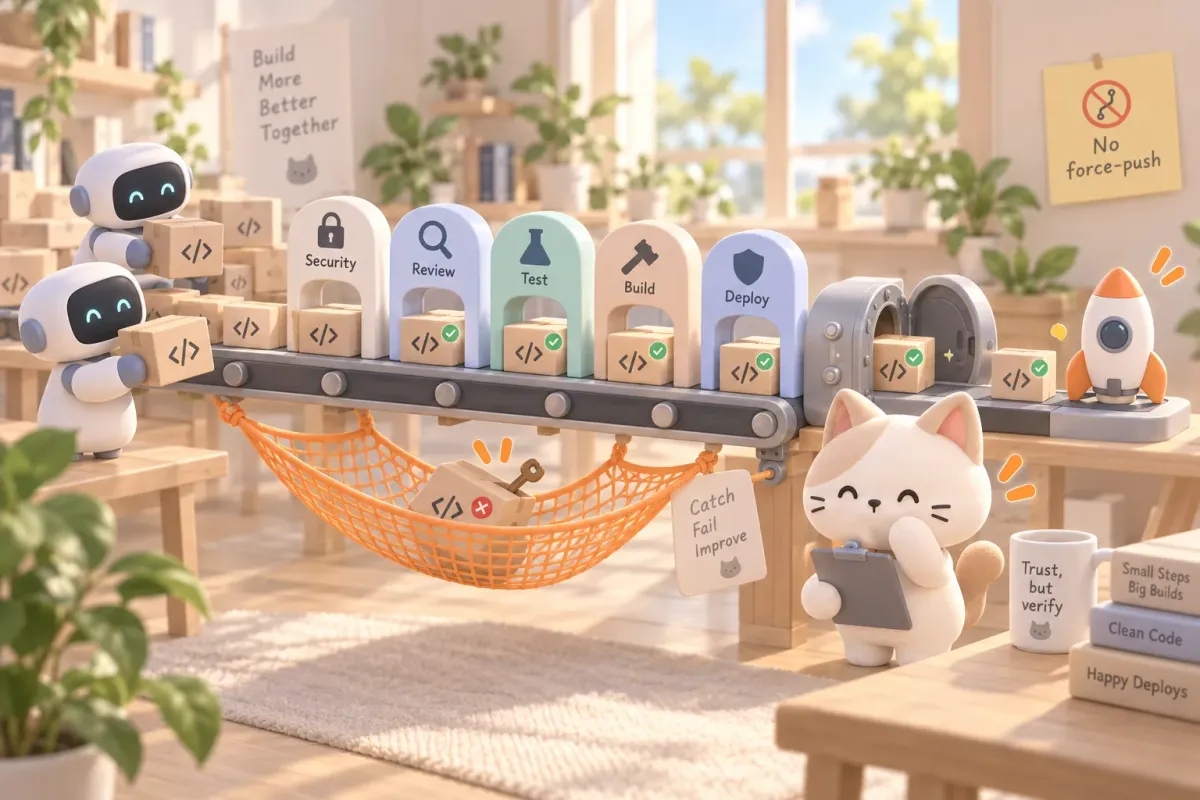
I stacked the safety net step by step: 8 phases, 15 jobs, from security to a GitOps lock (a setup where nothing deploys except through the deployment-config repo).
Result
Code reaches production only after secrets, quality, tests, dependencies, image vulnerabilities, and the deploy path all pass. Each real incident added another rule.
The Full Map of 15 CI Jobs
AlgoSu's CI pipeline is composed of 15 jobs. These jobs don't run independently. They have strict dependency relationships. If any single one fails, subsequent stages are blocked.
Trigger
push / PR → main
Security Gate
gitleaks · paths-filter · .env blocking
Quality
ESLint+tsc × 5 / ruff / next-lint
Test
Jest × 5 / pytest / Vitest (coverage)
Audit + Build
npm audit × 6 → Docker ARM64 × 8
Trivy Scan
CRITICAL/HIGH × 8 images → SARIF
Deploy
deployment-config repo (aether-gitops) tag → ArgoCD sync
Notify
Grafana deployment annotation (marks the deploy time on Grafana dashboards)
This box groups the run into eight stages; the Phase 1–8 sections below follow the order of explanation instead, so their numbers don't line up with the box.
Dependency graph of the 15 CI jobs
Phase 1: Secret Scan
The first gate of the pipeline is security. For every push and PR, a security scan runs before the code is even tested.
gitleaks: Secret Leak Detection
- name: Run gitleaks secret scan
  run: |
    if [ "${{ github.event_name }}" = "pull_request" ]; then
      gitleaks detect --source . --config .gitleaks.toml \
        --log-opts "${{ github.event.pull_request.base.sha }}..${{ github.event.pull_request.head.sha }}" \
        --verbose
    else
      gitleaks detect --source . --config .gitleaks.toml --verbose
figitleaks, a secret-detection tool, scans the entire Git history for API keys, passwords, and tokens embedded in commits. For PRs, it scans only the changed commit range; for pushes, it scans everything.
One of the most common mistakes AI makes when generating code is leaving hardcoded tokens in example code. A human would think, "Oh, this is just an example, so I shouldn't use a real token." But AI can miss that contextual judgment. gitleaks catches those mistakes.
.env File Commit Blocking
- name: Reject committed .env files
  run: |
    VIOLATIONS=$(git ls-files | grep -E '(^|/)\.env($|\..*)' | grep -v '\.env\.example' || true)
    if [ -n "$(echo "$VIOLATIONS" | tr -d ' ')" ]; then
      echo "::error::SECURITY VIOLATION: .env files detected in Git"
      exit 1
fi.env files should be in .gitignore, but they can sneak in if someone accidentally runs git add -A or modifies .gitignore. This check explicitly verifies whether any .env file exists in the Git index. .env.example is allowed; everything else is blocked.
Why is this needed separately from secret-scan? gitleaks inspects file content patterns, but it doesn't check for the existence of .env files themselves. Since having an environment variable file committed is risky regardless of whether it contains secrets, we block the file's very existence.
Phase 2: Change Detection
AlgoSu is a monorepo. Six backend services + one frontend + one blog (AlgoSu's internal blog that shows decision records as web pages), all in a single repo. Building every service every time would be wasteful, so we use the dorny/paths-filter mentioned above to detect only the services that actually changed.
filters: |
  gateway:
    - 'services/gateway/**'
  identity:
    - 'services/identity/**'
# ... (path definitions for each of 8 services/modules)The outputs of this job (gateway: true/false, identity: true/false, etc.) are used in the if conditions of all subsequent jobs. Tests, linting, and builds for unchanged services are all skipped.
One important point: when manually triggered via workflow_dispatch, we provide an option that forces every service to rebuild regardless of changes (rebuild_all). It is a safety mechanism for cases like infrastructure changes or base image updates, where everything needs rebuilding.
Phase 3: Quality Gate
Linting and type checking run for services where changes were detected. They split into three tracks.
Node.js Services (5, matrix strategy)
quality-nestjs runs 5 services in parallel using a matrix strategy (copying the same job once per service, each with its own settings).
- Gateway, Identity, Submission, Problem: ESLint + TypeScript
tsc --noEmit - GitHub Worker: ESLint (
src/**/*.ts) + TypeScripttsc --noEmit
The matrix is designed flexibly so each service can have different has_eslint and lint_glob options.
Python Service (ai-analysis)
quality-python uses ruff. It performs both linting (ruff check) and format checking (ruff format --check). In Python projects, ruff is essentially flake8 + black + isort combined into one tool, making tooling management much cleaner.
Frontend (Next.js)
quality-frontend runs next lint + tsc --noEmit. Next.js's built-in linter includes React-specific rules, so it's sufficient without a separate ESLint configuration.
Phase 4: Test Matrix
Tests only run after passing the quality gate. Dependencies like needs: [detect-changes, quality-nestjs] mean that if linting fails, tests don't even start.
test-node (Jest x 5)
Four NestJS services and the GitHub Worker, written in plain Node.js, are tested in parallel via matrix. All services have --coverage --ci flags, and coverage results are uploaded as artifacts.
strategy:
  fail-fast: false
  matrix:
    include:
      - service: gateway
        test_args: '--coverage --ci'
      - service: identity
        test_args: '--coverage --ci --passWithNoTests'
      - service: submission
        test_args: '--coverage --ci --forceExit'
# ...fail-fast: false is important. Even if one service's tests fail, the rest continue testing. This is because seeing all failures at once makes debugging far more efficient.
test-ai-analysis (pytest)
The FastAPI service is tested with pytest, outputting coverage in XML format via --cov=src --cov-report=xml.
test-frontend (Vitest)
The frontend is tested with Vitest, using --ci --coverage flags optimized for CI environments.
Phase 5: Dependency Audit
audit-npm runs in parallel with tests. It performs npm audit across 6 Node.js projects (5 backend + 1 frontend).
- name: npm audit (high/critical)
run: npm audit --audit-level=critical --omit=dev--audit-level=critical blocks only critical-level vulnerabilities. The step name still says high, but the actual threshold is critical. --omit=dev excludes development dependencies. Blocking vulnerabilities in devDependencies that never reach production would cause CI to break far too often.
Phase 6: The Build Gate
The build job's conditions reveal the philosophy of this pipeline.
build-services:
  needs: [detect-changes, test-node, test-ai-analysis, audit-npm, secret-scan]
  if: |
    !cancelled() &&
    (needs.test-node.result == 'success' || needs.test-node.result == 'skipped') &&
    (needs.test-ai-analysis.result == 'success' || needs.test-ai-analysis.result == 'skipped') &&
    (needs.audit-npm.result == 'success' || needs.audit-npm.result == 'skipped') &&
needs.secret-scan.result == 'success'Here's what these conditions mean:
- secret-scan must succeed unconditionally. Not even
skippedis allowed. The secret scan can never be bypassed under any circumstances. - test and audit must be either success or skipped. Since tests for unchanged services are skipped,
skippedis allowed. Butfailureis never tolerated. !cancelled()comes first. By default, GitHub Actions skips a job if any job in itsneedslist failed or was skipped. With!cancelled(), the job still runs after skipped upstream jobs and lets this condition decide, but it won't run if someone cancelled the workflow.
The frontend build follows the same pattern.
build-frontend:
  needs: [detect-changes, test-frontend, audit-npm, secret-scan]
  if: |
    !cancelled() &&
    needs.detect-changes.outputs.frontend == 'true' &&
    needs.test-frontend.result == 'success' &&
    (needs.audit-npm.result == 'success' || needs.audit-npm.result == 'skipped') &&
needs.secret-scan.result == 'success'For the frontend, tests must be success; not even skipped is allowed. If changes were detected but tests were skipped, that's an abnormal situation.
ARM64 Cross Build
Docker images are built for the linux/arm64 platform because the deployment server is an Oracle Cloud (OCI) ARM instance (VM.Standard.A1.Flex). GitHub Actions runs on x86 runners, but QEMU + buildx cross-compiles ARM64 images.
Image tags follow the main-{git-sha} format. The latest tag is never used. We must always be able to trace which commit's image was deployed.
Phase 7: Image CVE Scan
Built images are not deployed immediately. Using Trivy, a container-image vulnerability scanner, trivy-scan scans all 8 images (6 backend + frontend + blog).
trivy image \
  --platform linux/arm64 \
  --severity CRITICAL,HIGH \
  --exit-code 1 \
  --ignore-unfixed \
  --format table \
"${{ env.IMAGE_PREFIX }}-${{ matrix.service }}:main-${{ github.sha }}"If CRITICAL or HIGH vulnerabilities are found, it returns exit code 1 and blocks the pipeline. --ignore-unfixed excludes vulnerabilities that don't yet have a patch. Results are also generated in SARIF, the standard format for static-analysis results, and uploaded to the GitHub Security tab.
Phase 8: GitOps Lock
A GitOps lock means deployment is tied to the deployment-config repo: nothing reaches production except through it.
Only images that pass all scans get deployed. But in AlgoSu, "deployment" doesn't mean pushing images directly to a server.
deploy:
  needs:
    - secret-scan
    - detect-changes
    - trivy-scan
    - build-services
    - build-frontend
    - build-blog
  if: |
    github.ref == 'refs/heads/main' && !cancelled() &&
    needs.secret-scan.result == 'success' &&
    needs.trivy-scan.result != 'failure' &&
    (needs.build-services.result == 'success' ||
     needs.build-frontend.result == 'success' ||
needs.build-blog.result == 'success')The deploy job does exactly one thing: update kustomization.yaml, the file listing each service's image tag, in the deployment-config repository (aether-gitops), a repo that holds only deployment settings. ArgoCD, a tool that keeps the cluster in line with what is in Git, then detects the change and syncs it to the k3s (lightweight Kubernetes) cluster. Deploying by whatever is written in Git like this is called GitOps.
# aether-gitops/algosu/overlays/prod/kustomization.yaml
for SVC in $UPDATED; do
  python3 -c "
import yaml
with open('kustomization.yaml', 'r') as f:
    data = yaml.safe_load(f)
for img in data.get('images', []):
    if 'algosu-${SVC}' in img.get('name', ''):
        img['newTag'] = 'main-${SHA}'
with open('kustomization.yaml', 'w') as f:
    yaml.dump(data, f, default_flow_style=False, sort_keys=False)
"
doneThe advantage of this architecture is that the source code repo and the deployment repo are separated. No matter how many mistakes are made in the source repo, production deployments are unaffected unless the deployment-config repo is directly modified.
Sequential Rollout on the Deployment Server
Day-to-day deployment is handled by ArgoCD. Rolling the services out one layer at a time, in the order below, is the order built into the deploy.sh script that ran directly on the deployment server (the k3s cluster) before ArgoCD came in.
L0 Infrastructure
PostgreSQL · Redis · RabbitMQL1 Identity
Authentication (dependency for other services)L2 Business
Problem + SubmissionL3 Async
GitHub Worker + AI AnalysisL4 Gateway
Routing + external entryL5 Frontend
Frontend + Ingress
Each layer only starts after the previous layer's rollout is complete. If a service fails, automatic rollback (kubectl rollout undo) is triggered. Infrastructure (Layer 0) cannot be rolled back, so a warning requiring manual intervention is printed on failure.
Incidents We Actually Hit
1. The Amend + Force-Push Trap
As mentioned earlier, git commit --amend followed by force-push causes dorny/paths-filter to miss changes. paths-filter compares the previous commit with the current one. But amending gives the commit a new SHA, so the previous commit that paths-filter uses as its baseline disappears from the remote branch.
Resolution: Force-push was banned across the entire project. If a fix is needed, make a new commit. Giving up a tidy commit history has a cost, but a safe CI pipeline is more important than a clean history.
2. The Risk of Manual Tag Changes in the Deployment-Config Repo
Once, I needed a quick deployment and manually edited kustomization.yaml in the deployment-config repo. I changed the image tag directly, but the image corresponding to that tag didn't exist in GHCR, GitHub's container registry. ArgoCD synced the manifest, but k3s couldn't pull the image, and the Pod fell into ImagePullBackOff (failing to fetch the image and retrying over and over).
Resolution: When manually modifying the deployment-config repo, always verify that the corresponding image exists in GHCR first.
3. Verifying That Environment Variables Were Actually Injected
I changed manifests and deployed, but the service behaved strangely. Turns out I had added new environment variables to the source repo's k8s manifests but hadn't reflected them in the deployment-config repo. Since ArgoCD syncs that repo's manifests, changing only the source repo is useless.
Resolution: After deployment, always verify that environment variables were actually injected using kubectl exec -- printenv. And when changing source repo manifests, always update the deployment-config repo as well.
4. Principle of Least Privilege
At the top of the CI pipeline, there's this setting:
permissions: {}Default permissions are set to zero, and each job explicitly declares only the permissions it needs. secret-scan gets only contents: read; build-services gets only contents: read and packages: write. This way, even if a specific job is compromised, the blast radius is limited.
Balancing AI and CI
In the AlgoSu project, AI generated the bulk of the code. Twelve agents divided the work by role, and a lead agent coordinated the whole operation. But no matter how sophisticated the agent system became, final verification had to be handled not by humans but by an automated pipeline.
The 15 CI jobs asked these questions about AI-generated code:
- Were any secrets leaked? (secret-scan)
- Does code quality meet the standard? (quality-nestjs, quality-python, quality-frontend)
- Do tests pass? (test-node, test-ai-analysis, test-frontend)
- Are there dependency vulnerabilities? (audit-npm)
- Are there vulnerabilities in the built images? (trivy-scan)
- Is the deployment path secure? (deploy → deployment-config repo → ArgoCD)
Code could reach production only after passing every one of these gates.
The faster AI wrote code, the more my role shifted from writing code to designing systems that verify code. Speed demanded rigor, and human review alone clearly had its limits, so automated pipelines were essential.
Fifteen jobs may sound like a lot, but if even one had been missing, there would have been a production incident. I learned firsthand that safety nets work best when the mesh is tight.