 AI Agents
Sliding-Window Context Management for AI Agents
· AlgoSu
- #agent
- #documentation
- #sliding-window
- #context-optimization
- #claude-code
Decision Records at Sprint 152
AlgoSu has run through more than 150 sprints (short work cycles); I wrote this during the 152nd. I didn't write a decision record (ADR: a document noting what was decided and why) for every sprint from day one. That habit started around the 62nd sprint, when I began bundling each sprint's decisions and retrospective into a single file. Since then, the docs/adr/sprints/ folder has collected nearly 90 of them so far, from sprint-62.md through sprint-151.md.
Those aren't the only documents the agents read.
CLAUDE.md: the project rules file an agent reads automatically every session.claude/commands/agents/: one file per agent (a persona) describing each of the 12 agents' role and prohibitionsMEMORY.md: a running summary of past work, updated every sprint
Having all these records is a good thing. It's also a dangerous one.
I can't hand all of these to an agent every session.
This post is about admitting that simple fact. And about how, on top of that admission, I used a sliding window algorithm to slim down agent context. And about the small rules behind the last seven sprints in a row with zero regressions.
Memory Fades for Agents Too
First, something we have to admit: memory fades.
It does for humans. Why I added this enum six months ago, why I shipped that migration separately, why this function name is so awkward. Given enough time, we forget. Rereading the code won't tell you "why." Code only shows you "what."
Agents have it worse.
Every session, an agent starts with an empty context. The next session's agent knows none of it: what was agreed in the previous conversation, the regression fixed yesterday, where we decided last week that a shared value should live. It's like someone on their first day. A person who takes a few days off still remembers something; an agent remembers exactly nothing.
So at AlgoSu, I took documentation seriously early on, gathering everything that must not be forgotten into one place:
- decisions and their background went into per-sprint decision records,
- conventions that don't change went into
CLAUDE.md, - and each agent's role went into its persona file under
.claude/commands/agents/.
Documentation That Worked
Here's one small example.
Over seven sprints, from the 145th to the 151st, the checks that keep the same kind of monitoring mistake from coming back grew one at a time, to eight. Every regression caught once was written into the decision records as a rule, so the next sprint wouldn't get hurt in the same place.
The eight checks: metric names, labels, dashboard panel titles, dashboard variables, alert-rule labels, dashboard structure, whether a regex holds up against unusual input, and whether backend and frontend enum values match. Once a check was in place, that kind of mistake never came back in a later sprint.
Open sprint-145.md through sprint-151.md in order and you can see each sprint's "lessons" section flowing into the next sprint's "new patterns" section. The documents set a steady rhythm.
7sprints
Consecutive zero-regression
sprints 145–151
8
Accumulated checks
metric names → enum sync
17sprints
Branch rules followed
never committing directly to main
Not having to pay twice for a lesson already learned. That's the real saving in maintenance.
Problem
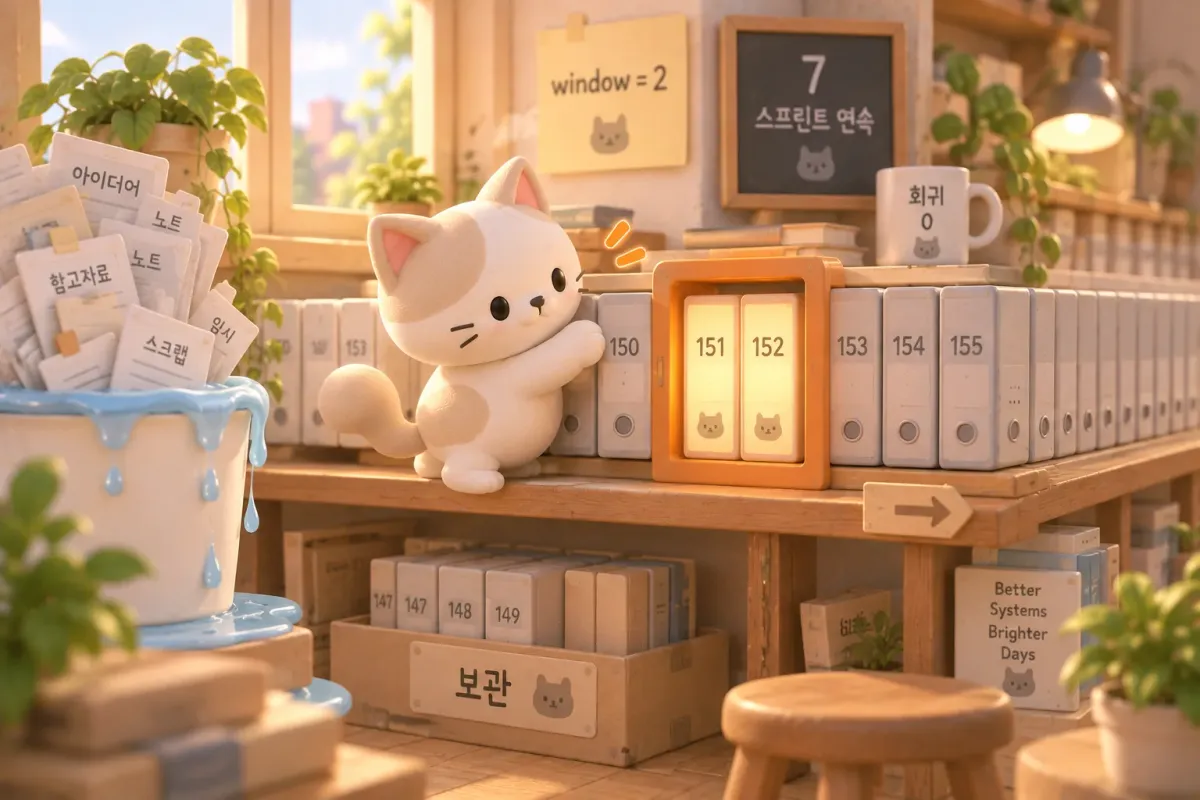
The growing pile of docs began eating the agent's context every session. It was like pouring water into an already-full bucket.
Decision
I decided to trim context with a simple rule borrowed from the sliding window algorithm.
Result
A 4-layer storage structure delivered seven sprints in a row without regression.
When Documents Became the Enemy
That was the happy part. The trouble came next.
About 40 sprints after I started keeping them, past the 100th sprint, the per-sprint decision records had reached nearly 40. That's when strange things started to happen. The amount of documentation an agent loaded into context at the start of each session had grown too large.
At first it felt like a point of pride: "Our project records every decision." But at some point the agent started missing the core. It broke rules clearly written in a decision record. It broke prohibitions clearly emphasized in CLAUDE.md.
The documents hadn't changed, yet they worked less and less over time.
The cause was simple.
I had been pouring water into a full bucket.
The Full Bucket: Context Limits
An LLM's context window isn't only about the token limit. Even within the limit, if there's too much in it, the model's attention spreads thin. This is known as lost-in-the-middle: rules buried in the middle of a long input get the least attention, and the one line that matters drowns in noise.
The more documents there were, the more often it happened. Here's what was going into every session before any work began:
[CLAUDE.md, 200 lines]
[MEMORY.md, 200 lines]
[ADR sprint-62 ~ sprint-151, ~10KB each]
[.claude/commands/agents/, 12 personas]
[docs/runbook/*.md, many]
[other domain documents]
─────────────────────────
Total: half the context budget filled before work even starts
Actual code + conversation space: the other half
Center of attention's gravity: nowhere in particularTokens may be left over, but the model's attention is finite. A hundred emphasized rules are weaker than one. If everything is marked important, nothing is.
But simply "cutting it down" was scary too. Any one decision record could hold the line that prevents the next sprint's regression. Chopping off the tail mechanically gives you no control over what you lose.
The Sliding Window Algorithm
The answer came from an algorithms textbook. More precisely, from the pattern I saw every week while building an algorithm study platform.
The sliding window algorithm doesn't hold every element of an array or stream at once. It keeps a window of fixed size, and when a new element comes in, the oldest one slides out. It's used for subarray sums, maximum subarrays, and network flow control. It's the standard way to handle an unbounded stream in bounded space.
[1, 2, 3, 4, 5, 6, 7, 8, ...]   ← input stream (unbounded)
   ┌───────┐
   │ 1 2 3 │                      ← window of size 3
   └───────┘
      ┌───────┐
      │ 2 3 4 │                   ← 1 slides out, 4 slides in
      └───────┘
         ┌───────┐
         │ 3 4 5 │                ← 2 slides out, 5 slides in
└───────┘Sprints are the same. We've passed 152 and they'll keep coming. It's an unbounded stream, and the context window is a bounded space. So: hold only what fits in the window, and pull the rest from a permanent store when needed.
That was the start.
sprint-window.md
The heart of it is a file called memory/sprint-window.md: a "what we're working on now" note that the agent reads first, every session. It isn't a shared repository file; it lives in a memory folder on my own machine that Claude Code, which runs the agents, loads automatically every session.
The window size is 2. The file looks like this:
---
name: sprint window
description: sliding window keeping only the last 2 sprints
status: active
---

## [1] Done — Sprint 151: Programmers SQL auto language select
- period, end_commit, merged PRs, work summary, Critic call results,
  validation, regression-blocking layers, new patterns, lessons, carry-over

## [2] In progress — Sprint 152: sliding window blog post
- start_commit, goal, planned tasks, owning agents[1] is the sprint that just finished, [2] is the one in progress. That's it. Anything older is outside the window.
I tried sizes 3 and 4 at first. More memory had to be better, right? It was the opposite. The bigger the window, the blurrier the in-progress work in [2] became. The agent got stuck on decisions that were too old, or pulled in old patterns that clashed with the most recent decision.
Size 2 was the right fit. The previous sprint's lessons stay sharp, and anything older is something you open on purpose, from its decision record, only when you need it.
One Field That Automates the Slide (status: idle | active)
How does the window slide? Automatically.
The status field in the file's header (frontmatter) acts as a state machine. The commands I run to start and stop a sprint, /start and /stop, change that value and slide the window as they do.
How sprint-window.md slides
/start fills [2] with the new sprint's details and sets status to active. /stop does more:
- The results of [2] (merged PRs, validation, lessons) move into [1], and the old [1] is pushed out
- The old [1] is saved permanently as
docs/adr/sprints/sprint-{N}.md - [2] becomes an empty slot for the next sprint
statusgoes back toidle
The agent works only inside the window; everything outside is the permanent store's job. A decision that moves into a decision record doesn't disappear. It just drops off the list of things loaded automatically every session, and can still be pulled up by its exact path whenever it's needed.
A 4-Layer Storage Structure
The sliding window alone wasn't enough. It decides what we hold right now, but everything outside the window has to live somewhere too. So I split storage into layers.
Four-layer storage
There are four layers: current work (the window), the table of contents (the index), fixed rules, and the permanent store. In the table below, the conventions row (CLAUDE.md) and the personas row together make up the "fixed rules" layer.
| Layer | File | How often it changes | Auto-loaded? | What it keeps |
|---|---|---|---|---|
| Window | sprint-window.md | every sprint | ✅ | last finished + in progress (size 2) |
| Index | MEMORY.md | every sprint | ✅ | a 1-line summary per sprint + link to the permanent store |
| Fixed rules: conventions | CLAUDE.md | rarely | ✅ | coding rules, prohibitions, security rules |
| Fixed rules: personas | .claude/commands/agents/ | rarely | ✅ | the 12 agents' roles and prohibitions |
| Permanent store | docs/adr/sprints/ | append-only | ❌ | every sprint's decisions and lessons |
The core idea is separating "where to forget" from "where to remember."
The agent's context is the place to forget. As the window slides, old things fall out naturally, so each session's attention gathers on the new work. The permanent store is the place to remember. A decision that lands there never disappears. It just isn't pulled in automatically. The exact path is always there.
MEMORY.md: An Index, Not the Content
MEMORY.md stays under 200 lines. It isn't the content. It's an index.
- Sprint 151 — Programmers SQL auto language select (2026-05-13):
  Backend Problem entity ProblemCategory enum + ... (1-line summary)
  ADR: [sprint-151.md](../../../../Desktop/leo.kim/AlgoSu/docs/adr/sprints/sprint-151.md)
- Sprint 150 — Carry-over seed cleanup (2026-05-13):
  Sprint 149 automation candidates, 3 PRs in a single day ...
ADR: [sprint-150.md](...)Each line only marks that a sprint happened; the content is in the decision record. When an agent wants to revisit a decision exactly, it follows the path from the index into the permanent store.
That way, each session loads one line per sprint instead of ~10KB of content per sprint. The difference is large.
CLAUDE.md and Personas: The Fixed Reference
These two barely change. Coding rules, prohibitions, security rules, and agent roles shouldn't shift from sprint to sprint.
In return, content that doesn't change is cheap to keep in context all the time. There's nothing new for the model to make sense of each time. A strong rule that stays put beats a weak rule that keeps changing. Choosing what to nail down mattered.
The .claude/commands/agents/ folder in particular moved into git in the 150th sprint. Before that, it was a local-only folder excluded from git. Copies on different machines kept drifting apart, so I put it in the repository, making it the single source of truth (SSoT) for all 12 agents' definitions.
Seven Sprints, Zero Regressions
In sprints 145–151, with the documents and the sliding window running together, the clearest change in the numbers was how often regressions happened.
8checks
Regression-blocking checks
added over sprints 145–151
7sprints
Consecutive zero-regression
evidence the docs are working
0
Branch rule violations
17 sprints since sprint 134 (no direct commits to main)
Of course, not all of this is the sliding window's doing. The two kinds of review described below and the division of work across 12 agents all played a part.
But the sliding window is what let those pieces work consistently. The previous sprint's lessons don't blur, and older decisions don't hold the present back. That balance was the foundation for blocking regressions.
Automated Review Works the Same Way
Two kinds of review appear in this post: automated review (Auto-Critic), which runs on every commit, and the final pre-merge review (Critic). In both cases the reviewing is done by Critic, a review agent. The agents run on Anthropic's Claude models, but Critic uses another company's coding model (OpenAI Codex, gpt-5) so the work gets a cross-check.
Automated review arrived in the 117th sprint. Whenever a commit changes code, it automatically queues a Critic review. The final pre-merge review checks a PR in round 1, round 2, and a round 3 if needed, before it merges.
Critic sorts what it finds into blockers (P0), critical issues (P1), and recommended fixes (P2). The fix goes back to the agent that owns that area.
What matters is that none of this cross-review weighs on the main session's context. Codex runs as a separate process and only a summary comes back. The main session's context window stays as it was.
It's the same philosophy as the sliding window: "Only when needed, only as much as needed, keep the main context light."
In the 151st sprint alone, automated review ran four times and the main context felt no different from usual. All four runs found no P0 or P1 issues and a single P2, which was fixed in round 2; every run ended clean. (sprint-151.md records the whole process.)
Forgetting as a Way to Remember
At first I thought, "If only I could remember everything." Push every decision record, every note, every decision and lesson into context each session, and the agent would work smarter.
The opposite happened. The more I pushed in, the blurrier the agent got. If everything is important, nothing is. Pouring more into a full bucket only makes it spill; stacking more onto a full context only thins its attention.
What the sliding window taught me is that "what to forget" comes before "what to remember." Decide where things get forgotten, and where they're remembered becomes clear. The window forgets what's outside it, but the permanent store keeps it at an exact path, ready the moment it's needed.
Documents can pile up without end. The per-sprint decision records will go from nearly 90 to 100, and on to 200. But the window stays at 2. What an agent carries into each session doesn't get heavier. Only the depth of the permanent store and the clarity of the index grow.
Memory fades. That's why we need documents. But too many documents fade too. That's why we needed the sliding window. Learning to forget, in the end, was how you remember.
Next sprint and the one after, the window will keep turning at the same size, with different contents each time. That, I think, is how maintenance breathes. You have to breathe out as much as you breathed in before the next breath comes.