 Retrospective
Separating Markdown Decision Records for AI from HTML Versions for People
· AlgoSu
- #agentic-system
- #adr
- #context-engineering
- #documentation
- #llm
Recently I saw Andrej Karpathy (an OpenAI co-founder and former director of AI at Tesla) make a point along the lines of "for LLM output, HTML may serve people better than Markdown."
The reactions split roughly into two camps.
One saw it as a good direction: LLM output could go beyond plain text and become an interface people can read, understand, and work with directly.
The other worried about token cost. HTML has more tags than Markdown, so the output gets longer, and cost and latency can rise with it.
At first I also saw this debate as just a question of output format. Markdown or HTML. Conciseness or readability. Token efficiency or user experience.
But when I thought about AlgoSu's decision records, I realized the same problem was already happening inside my own project.
ADRs I Wasn't Reading
AlgoSu keeps accumulating decision records (ADRs: Architecture Decision Records, documents that note what was decided and why).
As I built features, changed structures, ran into failures, and fixed them, I recorded the important decisions as ADRs.
These documents were never meant for humans alone. If anything, the main goal was to keep the AI agents from losing the project's context, since an agent doesn't remember earlier conversations once a session ends.
Which decision was made and why, which structure we stopped using, which constraint the next task must respect: this is what agents need when they pick up the next piece of work.
So Markdown was a pretty good fit.
- It's text-based, so it's easy to manage in Git.
- The diffs are clean.
- There's little unnecessary decoration for an agent to read.
- It's more token-efficient than HTML.
- It's easy to keep as a structured document.
But there was a problem. I had almost stopped reading those documents myself.
The ADRs were piling up, and the reasons behind each decision were there. The agents could refer to them.
Yet I, the person running the project, rarely opened the Markdown ADRs when I needed to retrace how the project had evolved.
It wasn't that the documents didn't exist. They just weren't being read.
Written Is Not Read
Markdown is a good format. It's familiar to developers, easy to put in a repository, and fits well with code review. I've written most of my notes in Markdown too.
But over time, the ADRs kept getting longer.
As sprints and decisions piled up, opening a single Markdown document to follow the story became a chore.
The key decisions, the background, the scope of impact, and the follow-up work were all mixed together in the text. An agent could read it just fine, but for a person trying to skim and decide quickly, it was tiring.
I had to admit one thing.
A document being stored and a person being able to re-read that document are two different problems.
The point of an ADR isn't just "to leave a record." You need to be able to re-read it later, recover the reasoning behind the decision, and connect it to the decision in front of you now.
Otherwise the document stays in the repository but, for actual maintenance, it's as good as gone.
Docs for Agents, Docs for Humans
After running into this, the question of whether Markdown or HTML is better looked different.
What mattered wasn't the format. It was who reads the document.
AlgoSu's ADRs were playing two roles at once.
The first is agent memory: it lets the agents look up earlier decisions and constraints so they don't repeat the same mistakes.
The second is a review screen for humans: it's where I re-read how the project evolved and understand why the current structure ended up this way.
The problem is that these two readers want documents in different shapes.
Markdown for agents
- It's concise.
- The token cost is low.
- It's easy to parse.
- It fits well with Git-based workflows.
- Changes are easy to track through diffs.
Markdown alone, for people
- A long document has weak visual hierarchy.
- The important decisions don't stand out at a glance.
- It's hard to follow the story across several ADRs.
- It easily becomes a "document you should read but don't."
So the answer wasn't to drop Markdown and switch entirely to HTML. I had to separate the document's readers.
Splitting ADRs into Two Forms
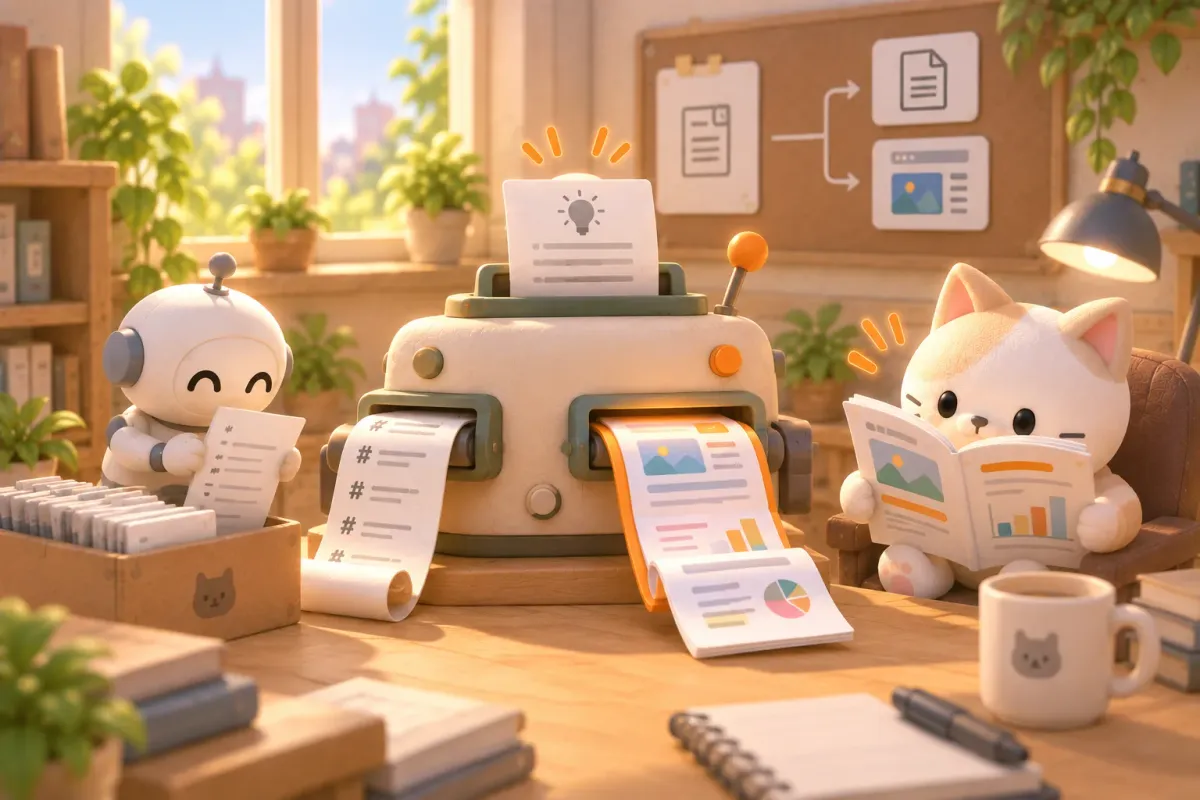
I didn't convert AlgoSu's ADRs to HTML wholesale. Instead, I changed it so the agent that writes each decision record also creates a new HTML version for people alongside the Markdown. The same record now exists in two forms.
One record, two forms
The Markdown ADRs stay as agent memory.
That way the agents can read earlier decisions, constraints, rules that prevent regressions, and follow-up work, and carry on with the next task. Here, conciseness and token efficiency still matter.
The HTML ADRs, on the other hand, are a review screen for people.
They break a long ADR into cards, sections, emphasis, and visual hierarchy so it's easy to re-read. The key decisions, background, impact, and follow-up work are visible at a glance.
In other words, I split one record into two views.
Rising Token Costs
Of course, this has a cost.
The output is larger than when generating Markdown alone. HTML tags and structure have to be generated too, so it uses more tokens.
In an LLM-based system, tokens are money. More output tokens mean higher cost and, sometimes, slower responses.
That concern is valid. I knew this change would use more tokens than before.
I chose it anyway, because I judged that this cost isn't waste but an investment in maintainability.
When Saving Tokens Backfires
When you build LLM systems, cutting tokens becomes important.
You trim unnecessary context, remove repeated output, keep only what the agent needs to read, and manage cost and latency.
But not every token you save is a good optimization.
When people stop reading the ADRs, the documents may still exist, but the project's context is gone.
Why this structure was chosen, why that approach was dropped, which constraint was added to prevent which failure, which decision shaped the structure that came after.
If a person can't recover that context, later debugging, refactoring, and feature work all get more expensive.
If you save tokens but people lose the system's memory, that may not be a real optimization.
I didn't add HTML ADRs to make pretty documents. I added them to give the project's memory a surface people can actually maintain from.
Documents as an Interface
This change made me rethink what a document is.
A document isn't just storage. Especially in a system where people work alongside AI agents, a document is closer to an interface that carries the project's memory between people and agents.
Agents read earlier context through documents; people reconstruct how the system evolved through them.
If so, there's no need to force the same shape on both readers. Agents need efficient documents. People need readable ones.
Markdown and HTML don't have to compete. They can be two forms for two different readers.
Conclusion
At first it looked like a question of whether Markdown or HTML is better.
But looking at AlgoSu's ADRs again, the question that mattered more to me was a different one.
Who does this document exist for?
A document for agents should be concise and efficient. A document for people should be re-readable.
So I didn't drop Markdown. I added HTML. Markdown stays as the agents' memory, and HTML serves as the review screen for people.
Token costs go up. But if people can re-read the system's memory, I see that cost as an investment in maintainability.