 Engineering
Why Janus Runs Three Concurrent Generations, Not Five
· Janus
- #local-llm
- #mlx
- #performance
- #kv-cache
Janus limits how many generation requests can go to the local model server at once. These are called generation slots, and sub-agents (workers), chat and verification share them. When the slots are full, no new worker is created, and the reason is recorded.
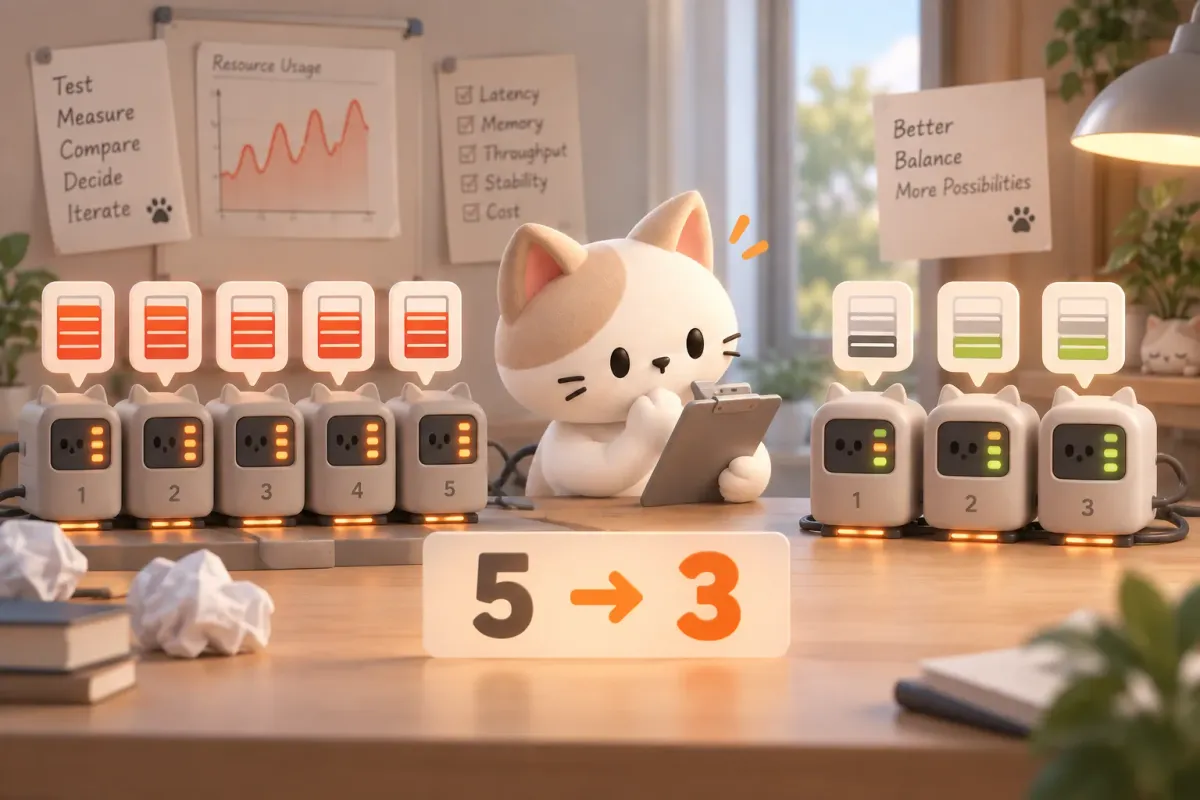
The default started at 5 and is now 3. This post covers why it changed and what has to happen before it goes up again.
Why it started at 5
When slots were added, the choice between 3 and 5 was left open and 5 shipped. It wasn't picked for a reason.
Why it went down to 3
The machine is an Apple Silicon Mac with 48GB of memory, running Qwen3.8 27B reduced (quantized) to 4-bit. Three things were checked.
KV cache is per request
The KV cache stores computations for earlier tokens. Each request gets its own, and with a 49K-token worker budget, one request can take 5 to 12GB in the worst case. Five of those at once run out of memory and start swapping.
One GPU limits the gain
On Apple Silicon, a single GPU (Metal) does all generation. Running several requests at once mainly helps by letting one generate while another waits on a tool, and that gain stops growing at 2 or 3.
More concurrency, less MTP benefit
MTP (multi-token prediction) predicts several tokens ahead and confirms them in one step. It only speeds things up when the predictions hold, and the hit rate drops as more requests run at once.
Actual usage said the same. Over that cycle, concurrent generation peaked at 3, and the p95 wait for a slot (the longest wait once the slowest 5% are set aside) was 0.012ms. Five was never needed.
5 → 3
Default generation slots
3
Measured peak concurrency
0.012ms
Slot wait p95
Raising it is decided by measurement
Along with lowering the default, Janus now shows when slots are actually short. There was already a function for "recalculate slots from GPU memory (VRAM) only when slot waits are a real bottleneck," but nothing called it at runtime, and no wait times were recorded for it to use, so that condition could never become true.
- Each time Janus's scheduler (the part that hands out slots to requests) grants a slot, the actual wait is recorded, up to the last 512. Tool and verification waits are kept out, because frequent tool waits would blur the p95.
- "Increase recommended" appears only when the p95 wait is at least 1 second with at least 10 recorded waits. The operations screen shows this verdict every 2 seconds.
- Only after that recommendation do you raise slots, in settings or with the
JANUS_MODEL_SLOTSenvironment variable. Settings allow 1 to 8.
The first time this ran on the real machine there were only 2 recorded waits, so the verdict was held as "insufficient samples." It followed the rule of not raising slots before the evidence is there.
Summary
With a local model, staying stable within memory came before running many requests at once. The default was set to 3 from both reasoning and measurement, and raising it waits until measured wait times show a need.