 AI Agents
Keeping an LLM from Making Up Investment Numbers
· FINCH
- #llm
- #guardrails
- #prompt-engineering
FINCH is an AI investment assistant that explains returns, risk and stock analysis based on what you hold and what you've traded. I led the AI part and built the AI server, and one rule was set from the start: the LLM never writes numbers itself.
Give an LLM some figures and ask for an explanation, and it will round 18.3% to "about 18%" or +0.87%p to "+0.9%p", or make up a number that isn't there. In investment information, one wrong number makes the whole explanation untrustworthy.
The placeholder structure
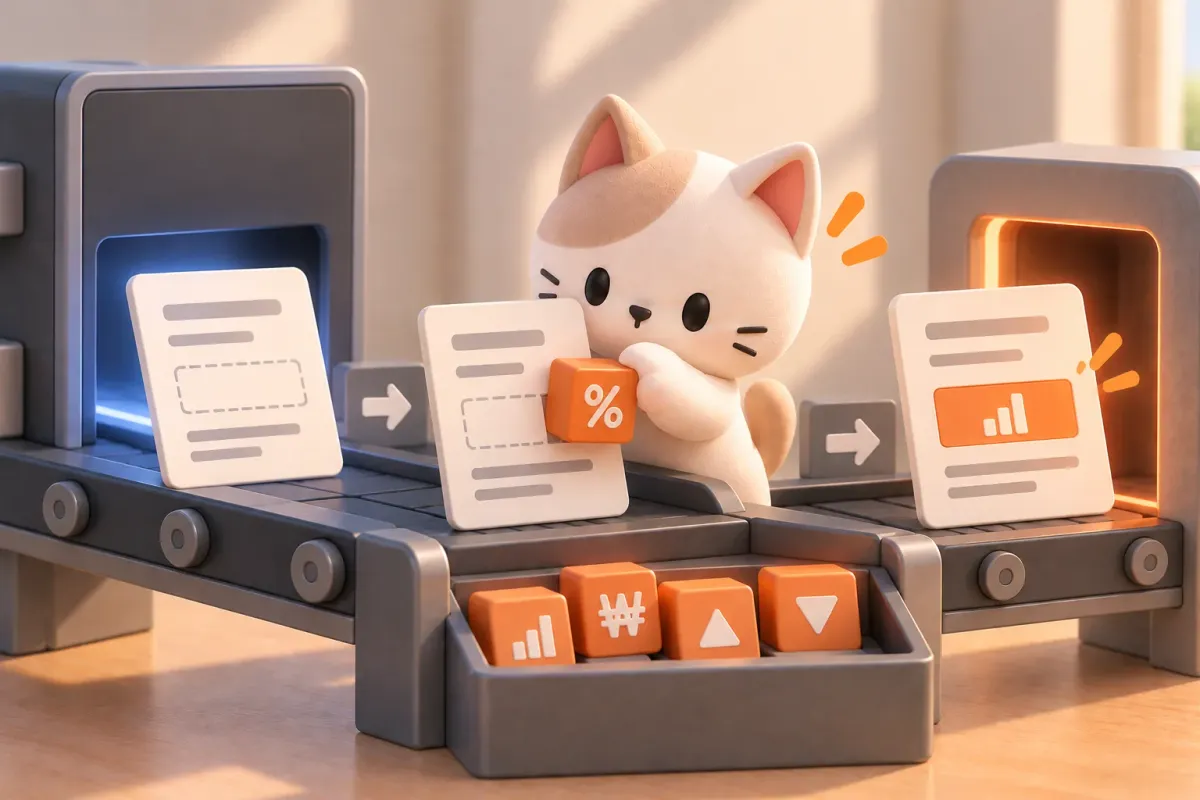
So the calculation engine produces the numbers, and the LLM only marks where a number goes.
Engine
Computes returns, weights and risk metricsKey list
Only the allowed placeholder keys go into the promptLLM writes
Uses {{key}} instead of numbersChecks
Rejects unknown keys and numbers written directlySubstitution
The server swaps keys for engine values
For example, the LLM writes "SK hynix {{return_000660}}" and the server replaces the key with "+3.4%" from the engine. The same pass splits the response into text segments and metric segments, so the UI can highlight the numbers on their own.
for match in _PLACEHOLDER_RE.finditer(narrative):
    segment = values.get(match.group(1))
    if segment is None:
        continue
    if match.start() > cursor:
        out.append(Segment.text(narrative[cursor : match.start()]))
    out.append(segment)
cursor = match.end()If a substituted value doesn't match the engine value, the response is blocked instead of regenerated. That means the pipeline is broken, not the model, and regenerating in the hope that it comes out right would be the wrong move.
After launch, this structure turned out to have three holes.
Hole 1: making the model fill in separate lists
The original response format asked for the text plus two separate lists: the placeholders used and the citations used. One day the stock analysis sections were all going out empty. That day's rejection reasons showed 102 citation-check failures. The model had copied the in-text notation into the lists, ^cit_1 and {{key}} instead of cit_1 and key, and the check only accepted bare ids.
I first made the check accept both notations, then went further and removed the lists. The text already contains every {{key}} and footnote, so the server can pull them out. Asking the model to keep a list in sync with its own text means writing the same thing twice, and when the two disagree, the section is thrown away. The response format went down to a single text field. We were about to switch to a smaller model to cut costs, so reducing what the model had to get right mattered.
Hole 2: writing the unit twice
Substituted values already carry their sign and unit (-0.40%p, 41.00%, 1,250 won). The model added the unit again anyway. The first card on the home screen said "비중은 41.00%%였습니다" (a weight of 41.00%%), and a performance breakdown said "-0.40%pp".
The segments made the cause obvious. The metric segment was "41.00%", and the text segment right after it started with "%". It wasn't a rendering bug; the model had written {{key}}%. The prompt already warned against this, so along with tightening the wording I added a check. Once values are substituted the placeholder boundary is gone, so the check runs on the text before substitution and looks for the same unit right after a {{key}}. Values without a unit are skipped, because some places need the model to add one (like {{trading_days}} followed by "days").
Hole 3: a path where no values came through
The last hole showed up just before the demo. Asked about holdings in chat, the assistant answered "I couldn't find per-stock return data." The tool was reading all 7 holdings correctly.
In this design, numbers from tools also have to be registered as placeholder values before they reach generation. That was on purpose, so no number can get around the rule. But the path that read account data from the backend never called the code that registers values. In production there were 7 holdings and 0 registered values, and the model was told "No numeric placeholders available. Do not mention numbers." It was following the rule exactly.
After the fix, 31 values were registered. I found one more thing along the way: keys end in a stock code, like return_000660, so the model sometimes wrote the code instead of the name ("000660: +3.4%"). Now a code-to-name table goes along with the request.
Before
"I couldn't find per-stock return data."
After
"SK hynix +3.4%, Korean Air +19.2%, Hyundai Motor -14.3%, …"
The fix came with 4 new tests, and I confirmed all 4 fail when the fix is reverted.
Summary
The placeholder structure stopped the LLM from making up numbers. The cost is that every number has to travel from the engine through placeholders, and if that path breaks anywhere, you get "I don't know" instead of a wrong answer. In all three holes, the model wasn't breaking the rule; the response format, a check or a data path didn't match it.