 Engineering
An External Monitoring Path That Works Even When the Node Fails
· PinLog
- #monitoring
- #failure-domain
- #kubernetes
- #observability
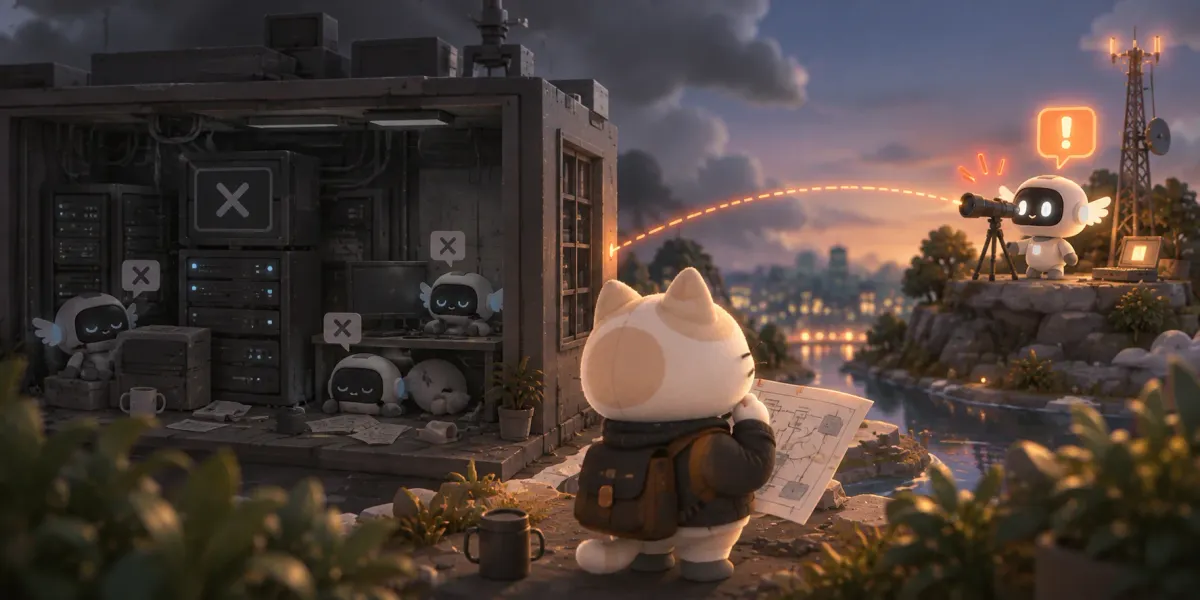
Once monitoring is installed on a server and alerts are connected, it can feel as though the system is ready to watch for failures. But change one question and a gap appears: if the server itself stops, rather than just the application, who sends the alert?
PinLog ran its k3s control plane and application workloads together on a single AWS node. k3s is a lightweight Kubernetes distribution, and the control plane is the set of components that manages the cluster.
Prometheus, which collects metrics, and Alertmanager, which handles alerts, ran on that node too. Both the system collecting service state and the system reporting it depended on the survival of the very server they watched.
Problem
Prometheus, Alertmanager, and Sentinel, the alert receiver on the host, all ran on the same single AWS node they were watching. If the whole node stopped, the alert path could stop with it.
Decision
The internal alert path stayed as it was. A separate external path was added: HTTPS/TLS checks run in a GitHub-hosted environment and send results directly to Mattermost.
Result
There is now a path that checks reachability from outside the node. It does not recover the service or make it highly available, and both paths still end at Mattermost.
Split Processes, Shared Failure
The useful concept here is a failure domain: the scope of components that one failure can affect together. The application and its monitoring can live in different Pods and separate namespaces, yet neither can execute when their shared node stops. Logical separation is not the same as independence from failure.
This does not make internal monitoring useless. While the node is running, it can observe resources and workload state and collect clues about problems. But if the last line of notification for a complete node failure also depends on that internal path, the alerting system can disappear at exactly the moment it is needed.
Adding an Outside Vantage Point
PinLog's internal alert path begins with metric collection and rule evaluation in Prometheus and passes through Alertmanager. A receiver called Sentinel Receiver, running on the host (the node's operating system, outside the cluster), then picks it up and delivers it to Mattermost, the team chat. The alert travels through these stages:
Prometheus
Collect internal metrics and evaluate rulesAlertmanager
Handle generated alertsHost Sentinel
Receive and process alerts on the hostMattermost
Present alerts to the operator
The important detail is that placing Sentinel on the host rather than inside the cluster does not make it independent of node failure. It runs at a different layer but relies on the same node. Moving to a host process crosses a boundary, but not the boundary that matters here: the failure domain of the whole node.
The external HTTPS/TLS monitor therefore runs in a GitHub-hosted environment (an execution environment operated by GitHub) and sends its results directly to Mattermost. It does not go through the service node's Prometheus or Sentinel. Rather than removing internal alerts or moving the entire observability stack, the design adds a separate path that checks reachability from outside the node.
GitHub-hosted execution
Start the check outside the service nodeHTTPS / TLS
Check service access from outsideMattermost
Deliver directly, bypassing the internal receiver
What matters is placement and dependencies more than the name of the execution service. Even a check performed outside the node runs into the same problem if its result must return to a receiver on the failed node. We need to follow not just where the check starts, but the entire route to the operator.
Two Paths, Not Duplicates
The internal and external paths answer different questions. Internal monitoring supplies clues about what is happening inside the service. External checks ask whether the service can be reached from outside. One provides information closer to the cause; the other observes an externally visible symptom.
Internal monitoring
Prometheus · Alertmanager · host Sentinel
Metrics and alerts describe internal state. Collection and delivery depend on the service node's execution environment.
External checks
GitHub-hosted HTTPS/TLS monitor
Checks access from outside the node. Bypasses the internal alert path, but does not explain the internal cause.
Adding more monitoring processes to the same node is not an adequate alternative for this problem. More processes remain exposed to the same complete node failure. Conversely, keeping only external checks would leave less information to explain internal state. The reason to retain both paths is not to accumulate duplicate tools, but to preserve different scopes of observation.
Failed Link, Not a Dead Node
An external monitor reporting failure does not by itself establish that the node has died. A complete node failure can cause a connection failure, but DNS problems, the network path, TLS configuration, or application response problems can also make an external check fail. The check reports an observed condition; the cause still needs investigation.
The first question when reading that signal should therefore be closer to “What failed, from which vantage point?” than “Is the server dead?” From there, checking whether internal metrics are available and whether the host can be reached can help narrow the scope. The external signal starts the investigation; it does not finish the diagnosis.
Being outside the node also does not mean independence from every possible failure. The external execution environment, network, and notification destination remain dependencies. In particular, both paths terminate at Mattermost. A check executing and a person receiving its alert are distinct things.
Boundaries Before Tools
The change I find important in this design is not the number of monitoring tools. It is the separation between a path that explains internal state and a path that can attempt an observation from outside when that interior stops. External monitoring does not recover the service or turn a single node into a highly available system. Expanding what we can learn and keeping the service running are separate tasks.
When reviewing monitoring architecture, I want to start by grouping the components that share a failure, rather than simply listing component names. Follow the route through collectors, rule evaluators, receivers, and the notification destination, asking at each step: “Could this still operate if this node were gone?”
When a server dies, the watcher inside it dies too. That is why checking where the watcher stands matters as much as looking more closely at what it watches.